▮ Local LLMs · fit · tokens/sec
Can your machine run it?
Match open-weight models to GPUs, Macs, and mini-PCs by memory fit and measured tokens/sec. Find out what to run on the machine you have, or what to buy next.
See what runs whereBrowse modelsPopular hardware
All devices → Mac Mini M416 GB unified memory~12.0 GB usable · $599 · $37/GB
- Mac Mini M4 32GB32 GB unified memory~24.0 GB usable · $999 · $31/GB
- Mac Mini M4 Pro24 GB unified memory~18.0 GB usable · $1399 · $58/GB
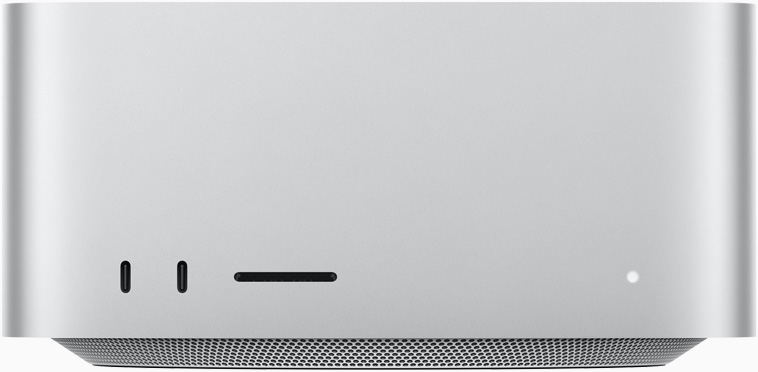 Mac Studio M5 Max36 GB unified memory~27.0 GB usable · $2500 · $69/GB
- Mac Studio M5 Ultra96 GB unified memory~72.0 GB usable · $5500 · $57/GB
 MacBook Pro M4 14-inch16 GB unified memory~12.0 GB usable · $1599 · $100/GB
- MacBook Pro M4 Max 16-inch48 GB unified memory~36.0 GB usable · $3999 · $83/GB
 NVIDIA RTX 409024 GB VRAM~21.6 GB usable · $1599 · $67/GB
Popular models
All models → Llama 3.1 8B8B parametersMeta Llama
 Mistral 7B7B parametersMistral AI
 Qwen 2.5 7B7B parametersAlibaba Qwen
Phi-414B parametersMicrosoft Phi
 Gemma 2 9B9B parametersGoogle Gemma
- Qwen 3 8B8B parametersAlibaba Qwen
- Qwen 3 32B32B parametersAlibaba Qwen
 Llama 3.1 70B70B parametersMeta Llama
Guides
All guides →- Quickstart: what runs whereOne grid of popular models against popular machines. Green runs, red doesn't, so you can see where the frontier sits.
- Mac or dedicated GPU?Unified memory versus VRAM: what each buys you in model size, speed, and price per GB.
- Quantization, in plain wordsWhat FP16, Q8_0, and Q4_K_M mean, and which one you should actually download.
- How much memory do I need?A quick rule of thumb for turning a parameter count into the GB you need.